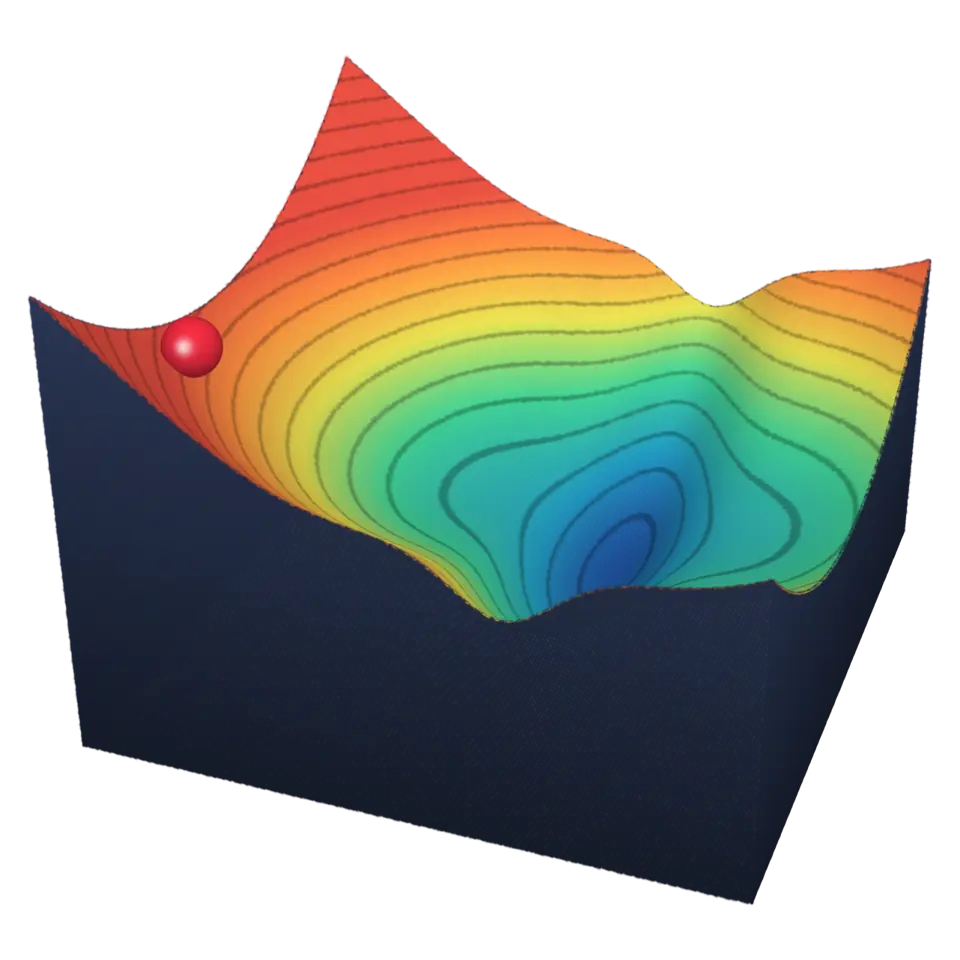
Fig. 38. §3 AI and Computing
Gradient Descent
Gradient descent is how most neural networks learn.
1Facts
- Shelf
- AI and Computing
- Kind
- Built from a recipe
- Sound
- Yes
- Hands-on
- Yes
- Licenses
- Own work (made in the page)
2How to play
Tap it to roll downhill. Hands-on: drop the ball anywhere; it rolls into a valley.
3Its controls
Table I. Every control on this Splash.
| Control | Kind | Range | Start |
|---|---|---|---|
| Roll downhill | Tap | ||
| Descend | Button | ||
| Learning rate | List | 3 choices | Just right |
4About it
Gradient descent is how most neural networks learn. Picture the network's error as a hilly landscape: the lower the ground, the better its answers. At each step, it works out the gradient, which points toward the steepest increase, and steps in the opposite direction. The learning rate sets how big each step is, and momentum lets it keep some speed from step to step.
Tap it: the ball takes 21 hopping steps downhill, leaving a trail of dots, overshoots the valley and settles in it. In the Splash tab, set the Learning rate: too low, and it creeps down the slope; too high, and it bounces from wall to wall; just right, and it settles. This prepared path illustrates the three settings; descent is not guaranteed to find the lowest valley of every landscape. With ✋ Hands-on on, press on the landscape and the ball comes to your finger; let go and it rolls downhill by the slope, overshoots a little and settles in the nearest valley, which is not always the deepest one.
5Details
- Splats
- Opens at 200,000 at Mid Detail, 60,002 at Low, and up to 810,000 at Max
6Is it right?
The paths are computed from a real loss function, finite-difference gradients, and momentum. They closely match independently derived analytic paths. They are then replayed, with hard boundaries and different momentum as well as learning rate.
Close.
The ball follows negative loss gradients with momentum.[1][2]
All 22 points in each of the three paths agree with analytic-gradient trajectories to absolute error below 0.000006 in position and plotted height.
Correct.
Momentum carries part of the previous update.[2]
The presets use learning rate and momentum pairs 0.035/0.3, 0.17/0.5, and 0.95/0.
Simplified.
The three paths are a limited example of learning-rate effects.[1][2]
The large step is clipped at the walls, and each choice can also change momentum; the graphic is not a guarantee of convergence on arbitrary losses.
- [1]Gradient descent, Dive into Deep Learning authors
- [2]Momentum, Dive into Deep Learning authors
- Simplified
- The path is computed once and replayed, not optimized during each tap. Positions are clipped to a fixed square. The learning-rate choices also change momentum, so they are not a controlled comparison of step size alone.
7Sources and credits
Made in Splashery. Its code is MIT.